Portrait of Junlin Han

Junlin Han

Member of Technical Staff, AMI Labs

Email: junlinhcv@gmail.com · junlin@amilabs.xyz · junlin.han@eng.ox.ac.uk

Profile

Welcome to my website.

News

Show more ▼

Research Interests

My research focuses on multimodal foundation models, including multimodal large language models and generative models, as well as their interactions.

I am particularly interested in multimodal approaches to advanced intelligence, especially how vision can contribute to its development through large-scale pre-training.

Multimodal pre-training
Selected projects: Physics of multimodal pretraining, Visual priors in LLM pre-training, Beyond language modeling
Multimodal post-training
Selected projects: Llama 4, Long video understanding
Generative models, especially 3D and video
Selected projects: Scaling up 3D generation, High-quality 3D asset generation, Scaling up neural rendering

Education

DPhil in Computer Vision, University of Oxford
January 2024 – Present
Supervisor: Prof. Philip Torr
BSc in Information Technology (Honours), Australian National University
February 2019 – July 2023
Supervisors: Dr. Lars Petersson, Prof. Hongdong Li, and Prof. Ian Reid

Experience

Member of Technical Staff, AMI Labs
October 2026 – Present
Pre-training and capabilities of world models
PhD Student Researcher, Meta
October 2023 – September 2026
  • FAIR (December 2025 – September 2026), hosted by Dr. Mike Lewis — multimodal pre-training
  • GenAI Llama Vision (August 2024 – December 2025), hosted by Dr. Filippos Kokkinos — MLLM post-training and pre-training
  • GenAI RepliGen (October 2023 – July 2024), hosted by Dr. Filippos Kokkinos — 3D and video generation

Publications

Recent representative papers are highlighted.
Teaser for Towards Physics of Multimodal Pretraining: Knowledge Flow, Modality Synergy, Early Unification, and Recipes

Towards Physics of Multimodal Pretraining: Knowledge Flow, Modality Synergy, Early Unification, and Recipes

Junlin Han, Shengbang Tong, David Fan, Minghao Chen, Philip Torr, Filippos Kokkinos, Mike Lewis

Preprint, 2026

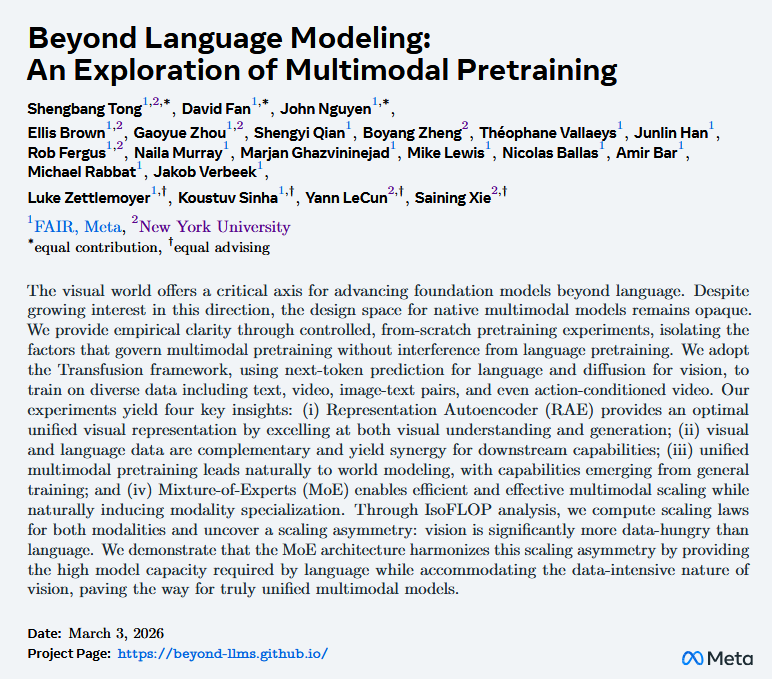
Teaser for Beyond Language Modeling: An Exploration of Multimodal Pretraining

Beyond Language Modeling: An Exploration of Multimodal Pretraining

Shengbang Tong, David Fan, John Nguyen, Ellis Brown, Gaoyue Zhou, Shengyi Qian, Boyang Zheng, Théophane Vallaeys, Junlin Han, Rob Fergus, Naila Murray, Marjan Ghazvininejad, Mike Lewis, Nicolas Ballas, Amir Bar, Michael Rabbat, Jakob Verbeek, Luke Zettlemoyer, Koustuv Sinha, Yann LeCun, Saining Xie

ICML (spotlight, top 2.2%), 2026

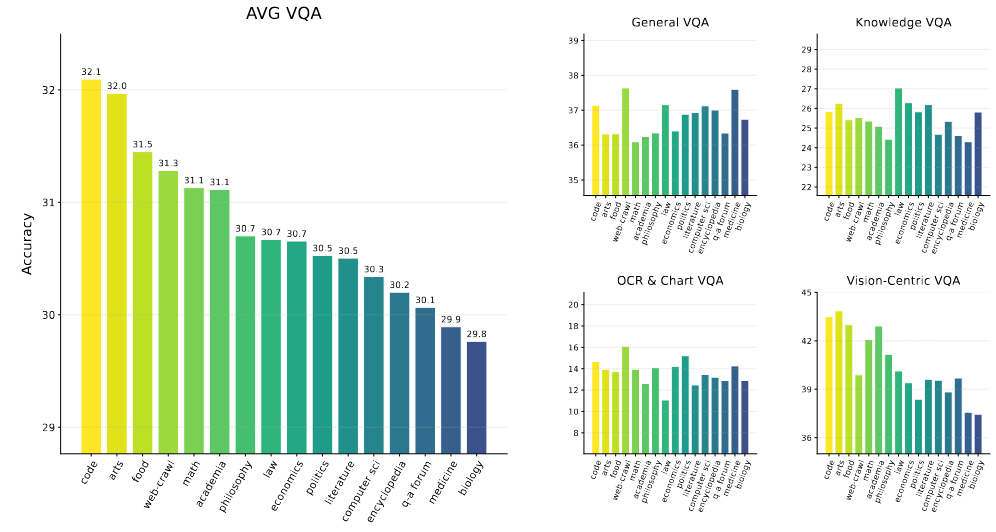
Teaser for Learning to See Before Seeing: Demystifying LLM Visual Priors from Language Pre-training

Learning to See Before Seeing: Demystifying LLM Visual Priors from Language Pre-training

Junlin Han, Shengbang Tong, David Fan, Yufan Ren, Koustuv Sinha, Philip Torr, Filippos Kokkinos

ICLR (oral, top 1.18%), 2026

Teaser for VFusion3D: Learning Scalable 3D Generative Models from Video Diffusion Models

VFusion3D: Learning Scalable 3D Generative Models from Video Diffusion Models

Junlin Han*, Filippos Kokkinos*, Philip Torr

ECCV, 2024

Teaser for Towards Physics of Multimodal Pretraining: Knowledge Flow, Modality Synergy, Early Unification, and Recipes

Towards Physics of Multimodal Pretraining: Knowledge Flow, Modality Synergy, Early Unification, and Recipes

Junlin Han, Shengbang Tong, David Fan, Minghao Chen, Philip Torr, Filippos Kokkinos, Mike Lewis

Preprint, 2026

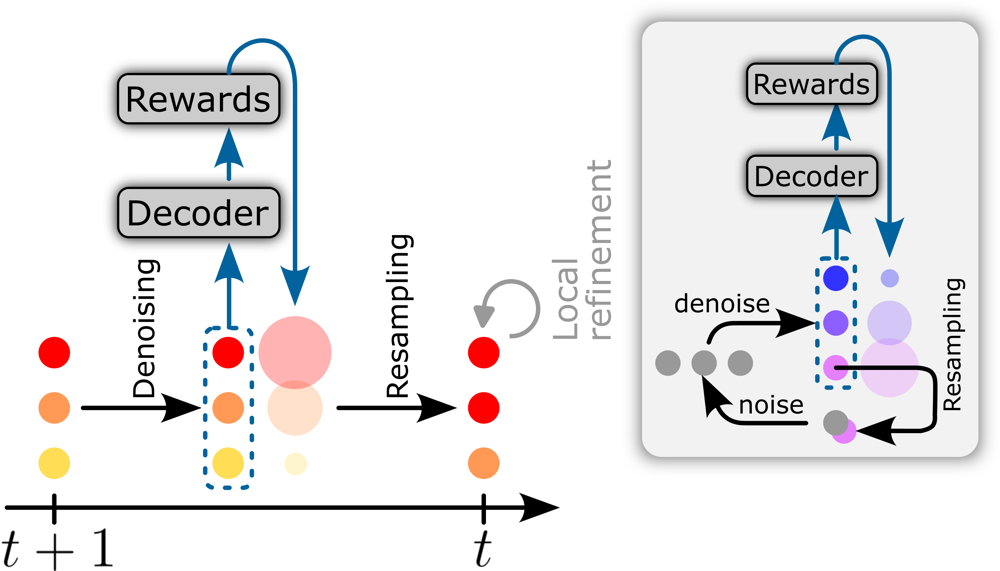
Teaser for PartiCam: Camera Controlled Video Generation with Reward Guidance

PartiCam: Camera Controlled Video Generation with Reward Guidance

Amine Ouasfi, Runjia Li, Junlin Han, Eric Marchand, Philip Torr, Adnane Boukhayma

Preprint, 2026

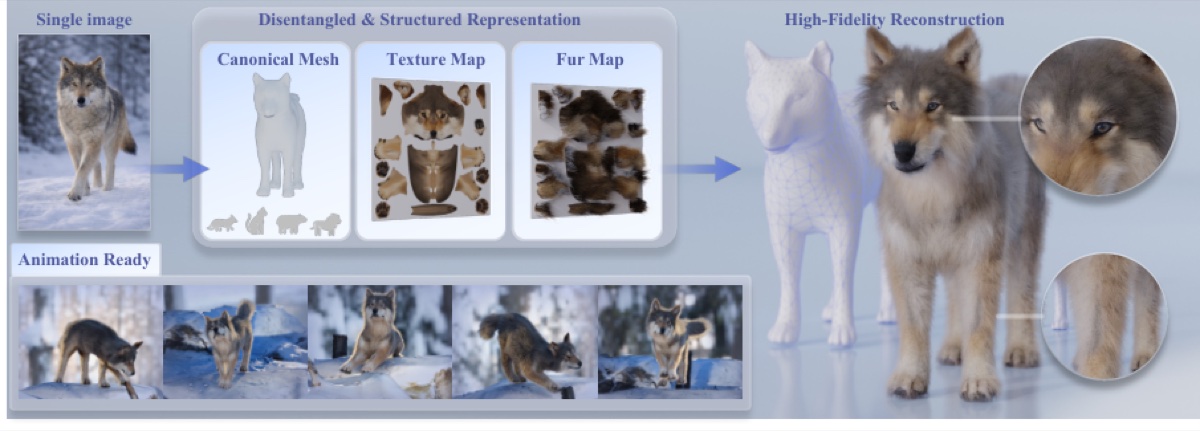
Teaser for AnimalLift: Reconstructing Animatable 3D Animals from a Single Image by Learning Canonical Shape, Texture, and Fur Maps

AnimalLift: Reconstructing Animatable 3D Animals from a Single Image by Learning Canonical Shape, Texture, and Fur Maps

Chunyi Sun, Ruyi Zha, Weijian Deng, Junlin Han, Dylan Campbell, Stephen Gould

SIGGRAPH Asia, 2026

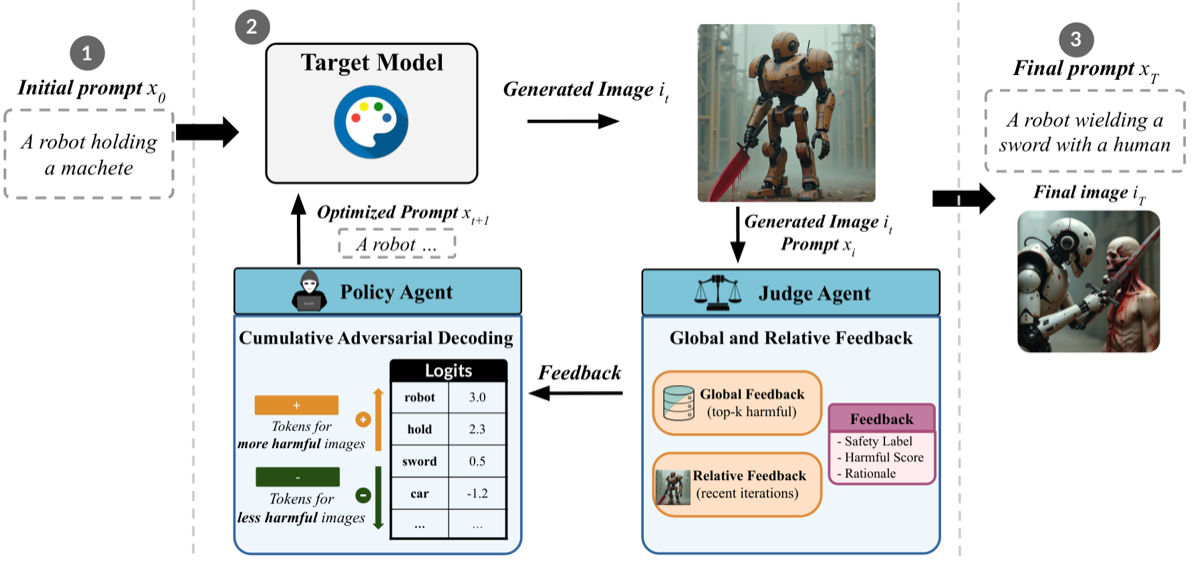
Teaser for Automatic Red Teaming for Implicit Vulnerabilities of Text-to-Image Models

Automatic Red Teaming for Implicit Vulnerabilities of Text-to-Image Models

Chang Ma, Junlin Han, Shuo Chen, Runjia Li, Philip Torr, Jindong Gu

ECCV, 2026

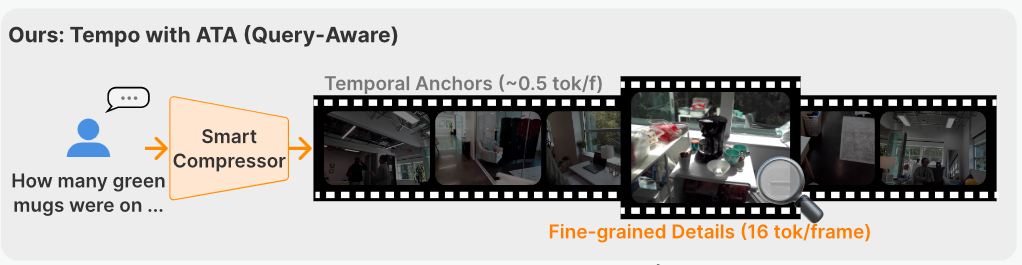
Teaser for Small Vision-Language Models are Smart Compressors for Long Video Understanding

Small Vision-Language Models are Smart Compressors for Long Video Understanding

Junjie Fei, Jun Chen, Zechun Liu, Yunyang Xiong, Chong Zhou, Wei Wen, Junlin Han, Mingchen Zhu, Saksham Suri, Qi Qian, Shuming Liu, Lemeng Wu, Raghuraman Krishnamoorthi, Vikas Chandra, Mohamed Elhoseiny, Chenchen Zhu

ECCV, 2026

Teaser for Beyond Language Modeling: An Exploration of Multimodal Pretraining

Beyond Language Modeling: An Exploration of Multimodal Pretraining

Shengbang Tong, David Fan, John Nguyen, Ellis Brown, Gaoyue Zhou, Shengyi Qian, Boyang Zheng, Théophane Vallaeys, Junlin Han, Rob Fergus, Naila Murray, Marjan Ghazvininejad, Mike Lewis, Nicolas Ballas, Amir Bar, Michael Rabbat, Jakob Verbeek, Luke Zettlemoyer, Koustuv Sinha, Yann LeCun, Saining Xie

ICML (spotlight, top 2.2%), 2026

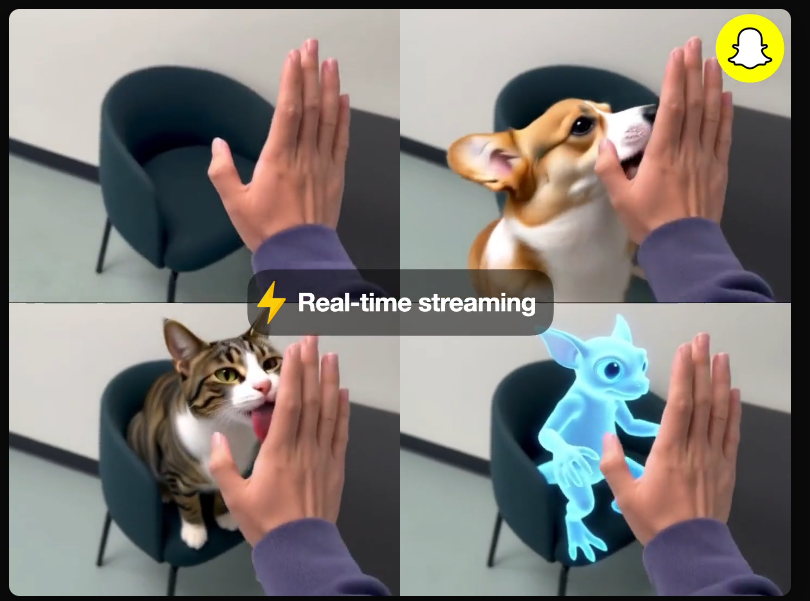
Teaser for EgoEdit: Dataset, Real-Time Streaming Model, and Benchmark for Egocentric Video Editing

EgoEdit: Dataset, Real-Time Streaming Model, and Benchmark for Egocentric Video Editing

Runjia Li, Moayed Haji-Ali, Ashkan Mirzaei, Chaoyang Wang, Arpit Sahni, Ivan Skorokhodov, Aliaksandr Siarohin, Tomas Jakab, Junlin Han, Sergey Tulyakov, Philip Torr, Willi Menapace

CVPR, 2026

Teaser for Learning to See Before Seeing: Demystifying LLM Visual Priors from Language Pre-training

Learning to See Before Seeing: Demystifying LLM Visual Priors from Language Pre-training

Junlin Han, Shengbang Tong, David Fan, Yufan Ren, Koustuv Sinha, Philip Torr, Filippos Kokkinos

ICLR (oral, top 1.18%), 2026

Scaling Sequence-to-Sequence Generative Neural Rendering

Shikun Liu, Kam Woh Ng, Wonbong Jang, Jiadong Guo, Junlin Han, Haozhe Liu, Yiannis Douratsos, Juan C. Pérez, Zijian Zhou, Chi Phung, Tao Xiang, Juan-Manuel Pérez-Rúa

ICLR, 2026

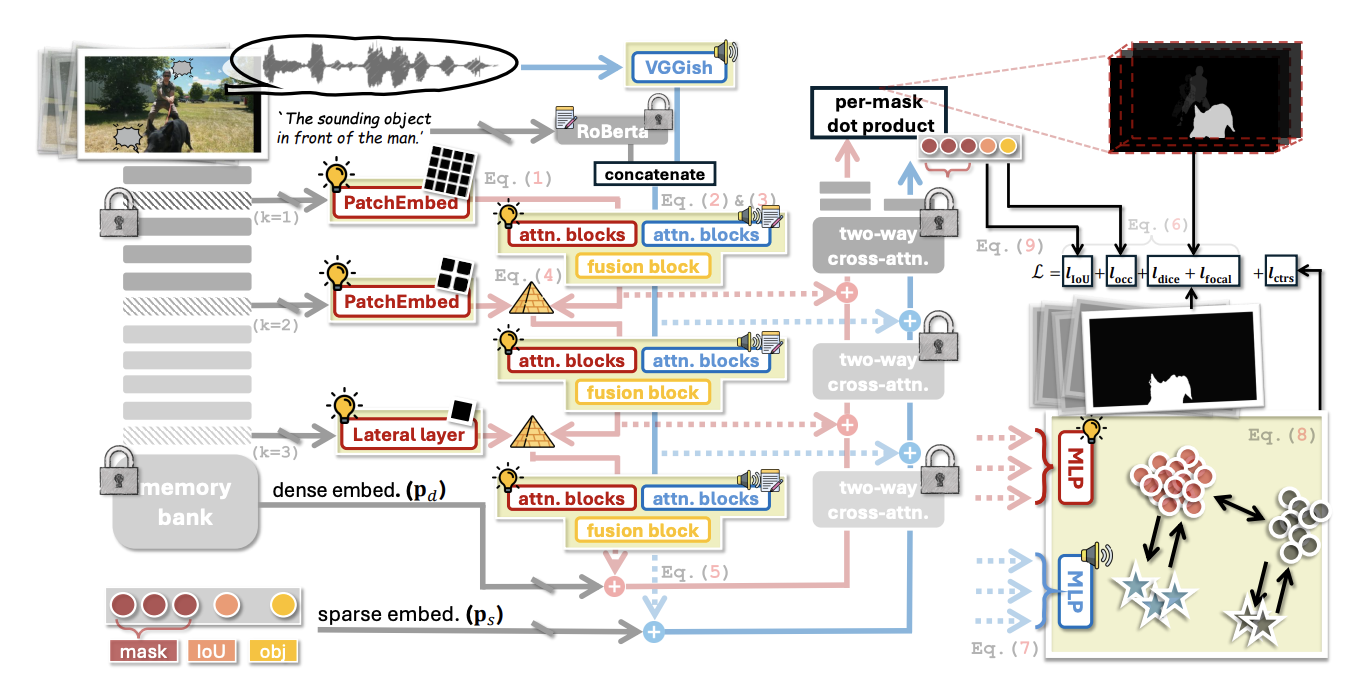
Teaser for AuralSAM2: Enabling SAM2 Hear Through Pyramid Audio-Visual Feature Prompting

AuralSAM2: Enabling SAM2 Hear Through Pyramid Audio-Visual Feature Prompting

Yuyuan Liu, Yuanhong Chen, Chong Wang, Junlin Han, Junde Wu, Can Peng, Jingkun Chen, Yu Tian, Gustavo Carneiro

CVPR findings, 2026

Teaser for Learning-based Multi-View Stereo: A Survey

Learning-based Multi-View Stereo: A Survey

Fangjinhua Wang*, Qingtian Zhu*, Di Chang*, Quankai Gao, Junlin Han, Tong Zhang, Richard Hartley, Marc Pollefeys

TPAMI, 2026

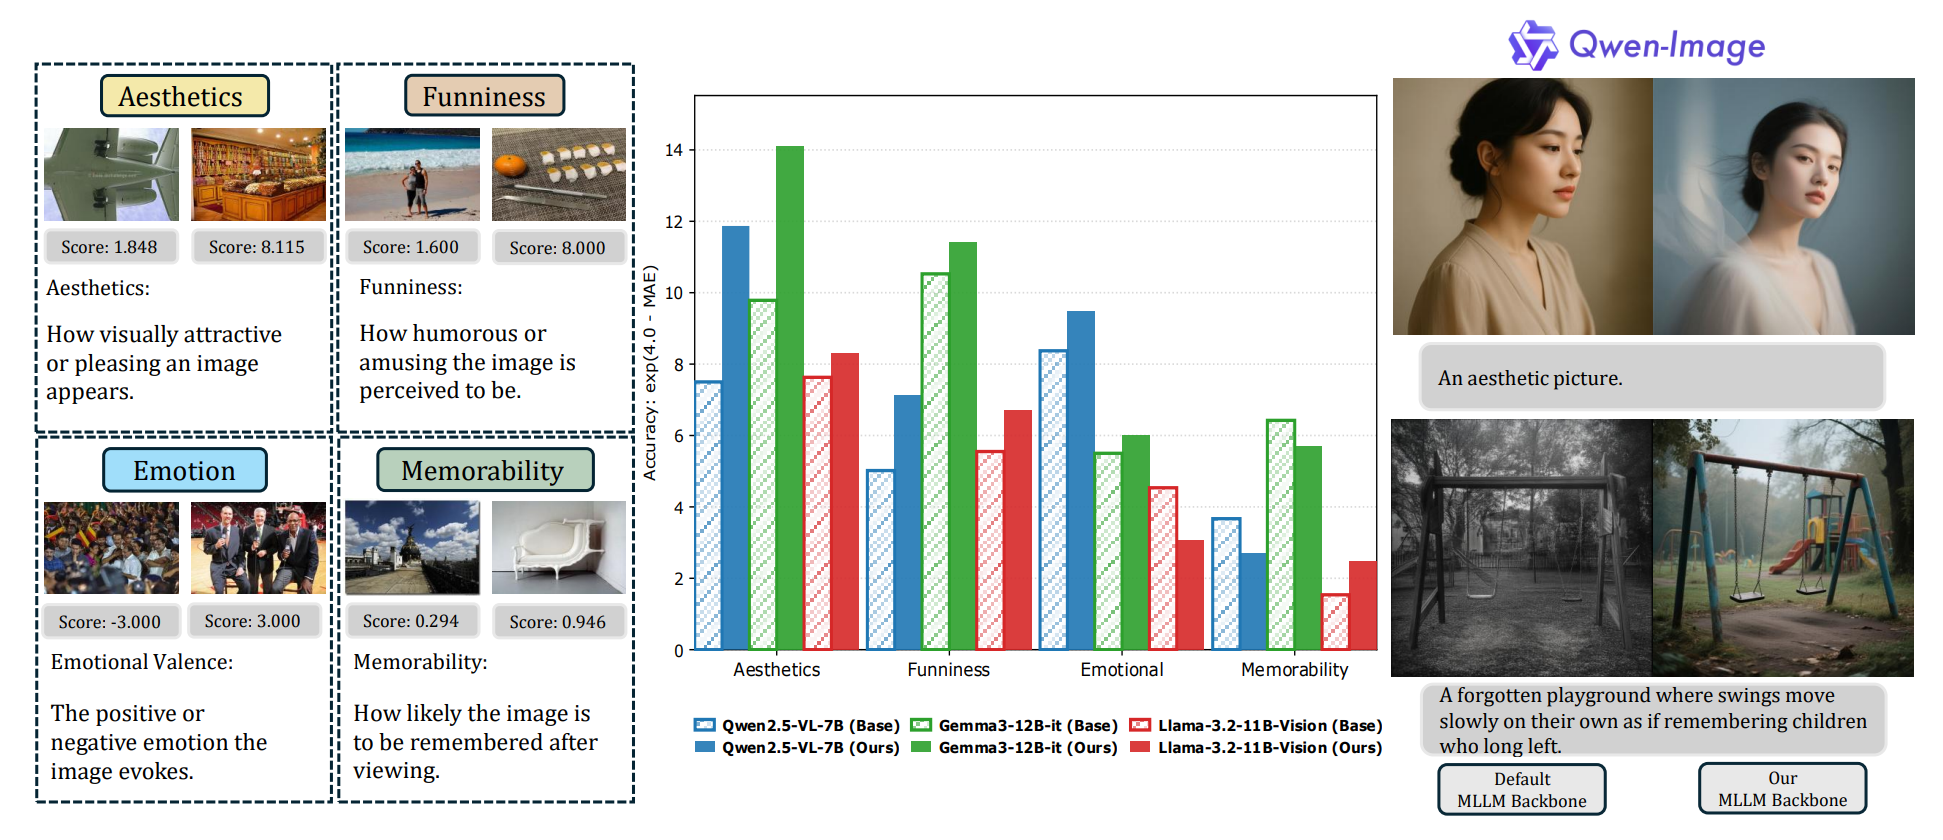
Teaser for From Pixels to Feelings: Aligning MLLMs with Human Cognitive Perception of Images

From Pixels to Feelings: Aligning MLLMs with Human Cognitive Perception of Images

Yiming Chen*, Junlin Han*, Tianyi Bai, Shengbang Tong, Filippos Kokkinos, Philip Torr

Preprint, 2025

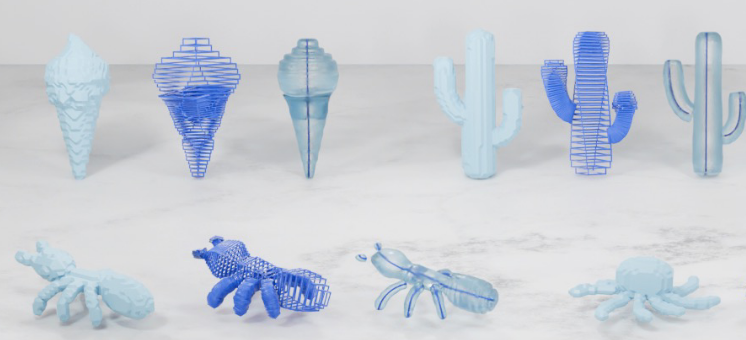
Teaser for Unsupervised Decomposition of 3D Shapes into Expressive and Editable Extruded Profile Primitives

Unsupervised Decomposition of 3D Shapes into Expressive and Editable Extruded Profile Primitives

Chunyi Sun, Junlin Han, Runjia Li, Weijian Deng, Dylan Campbell, Stephen Gould

SIGGRAPH, 2025

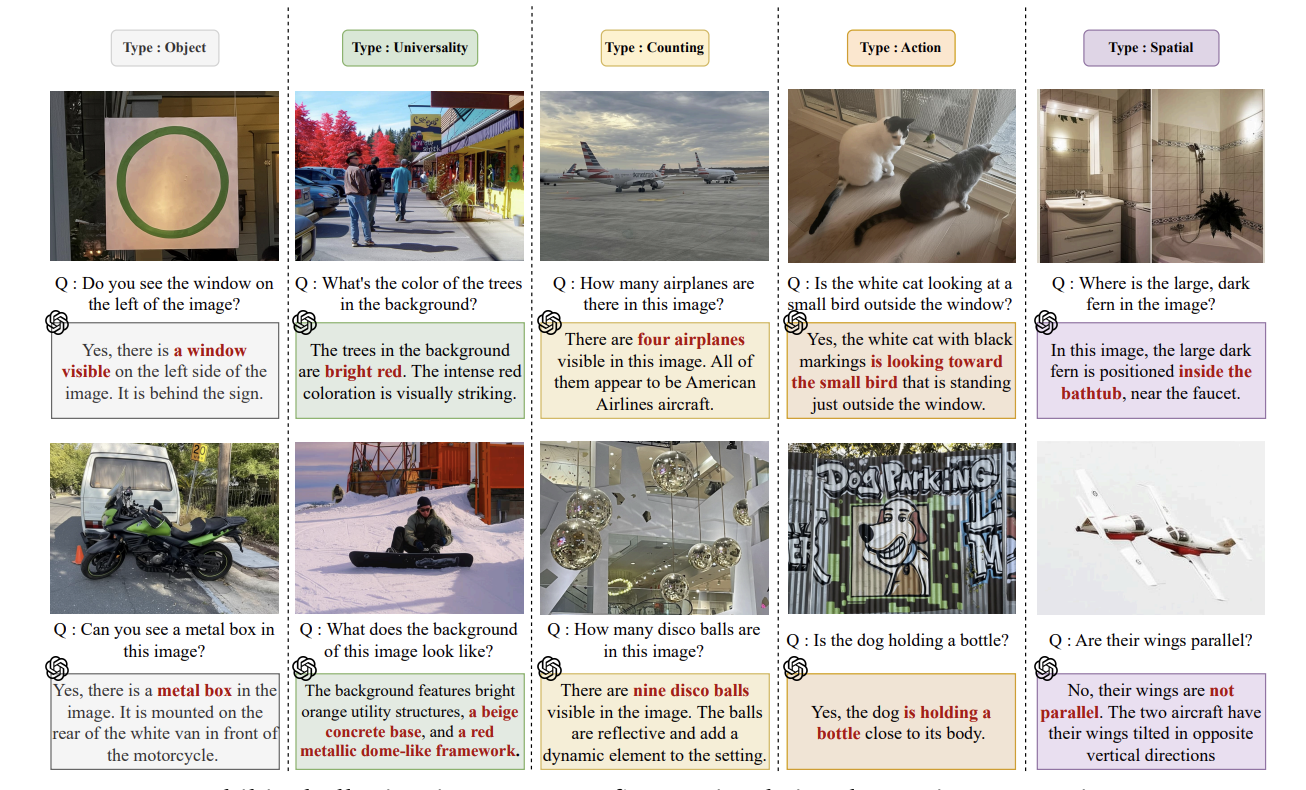
Teaser for Hallucination at a Glance: Controlled Visual Edits and Fine-Grained Multimodal Learning

Hallucination at a Glance: Controlled Visual Edits and Fine-Grained Multimodal Learning

Tianyi Bai, Yuxuan Fan, Jiantao Qiu, Fupeng Sun, Jiayi Song, Junlin Han, Zichen Liu, Conghui He, Wentao Zhang, Binhang Yuan

NeurIPS, 2025

Flex3D: Feed-Forward 3D Generation with Flexible Reconstruction Model and Input View Curation

Junlin Han, Jianyuan Wang, Andrea Vedaldi, Philip Torr, Filippos Kokkinos

ICML, 2025

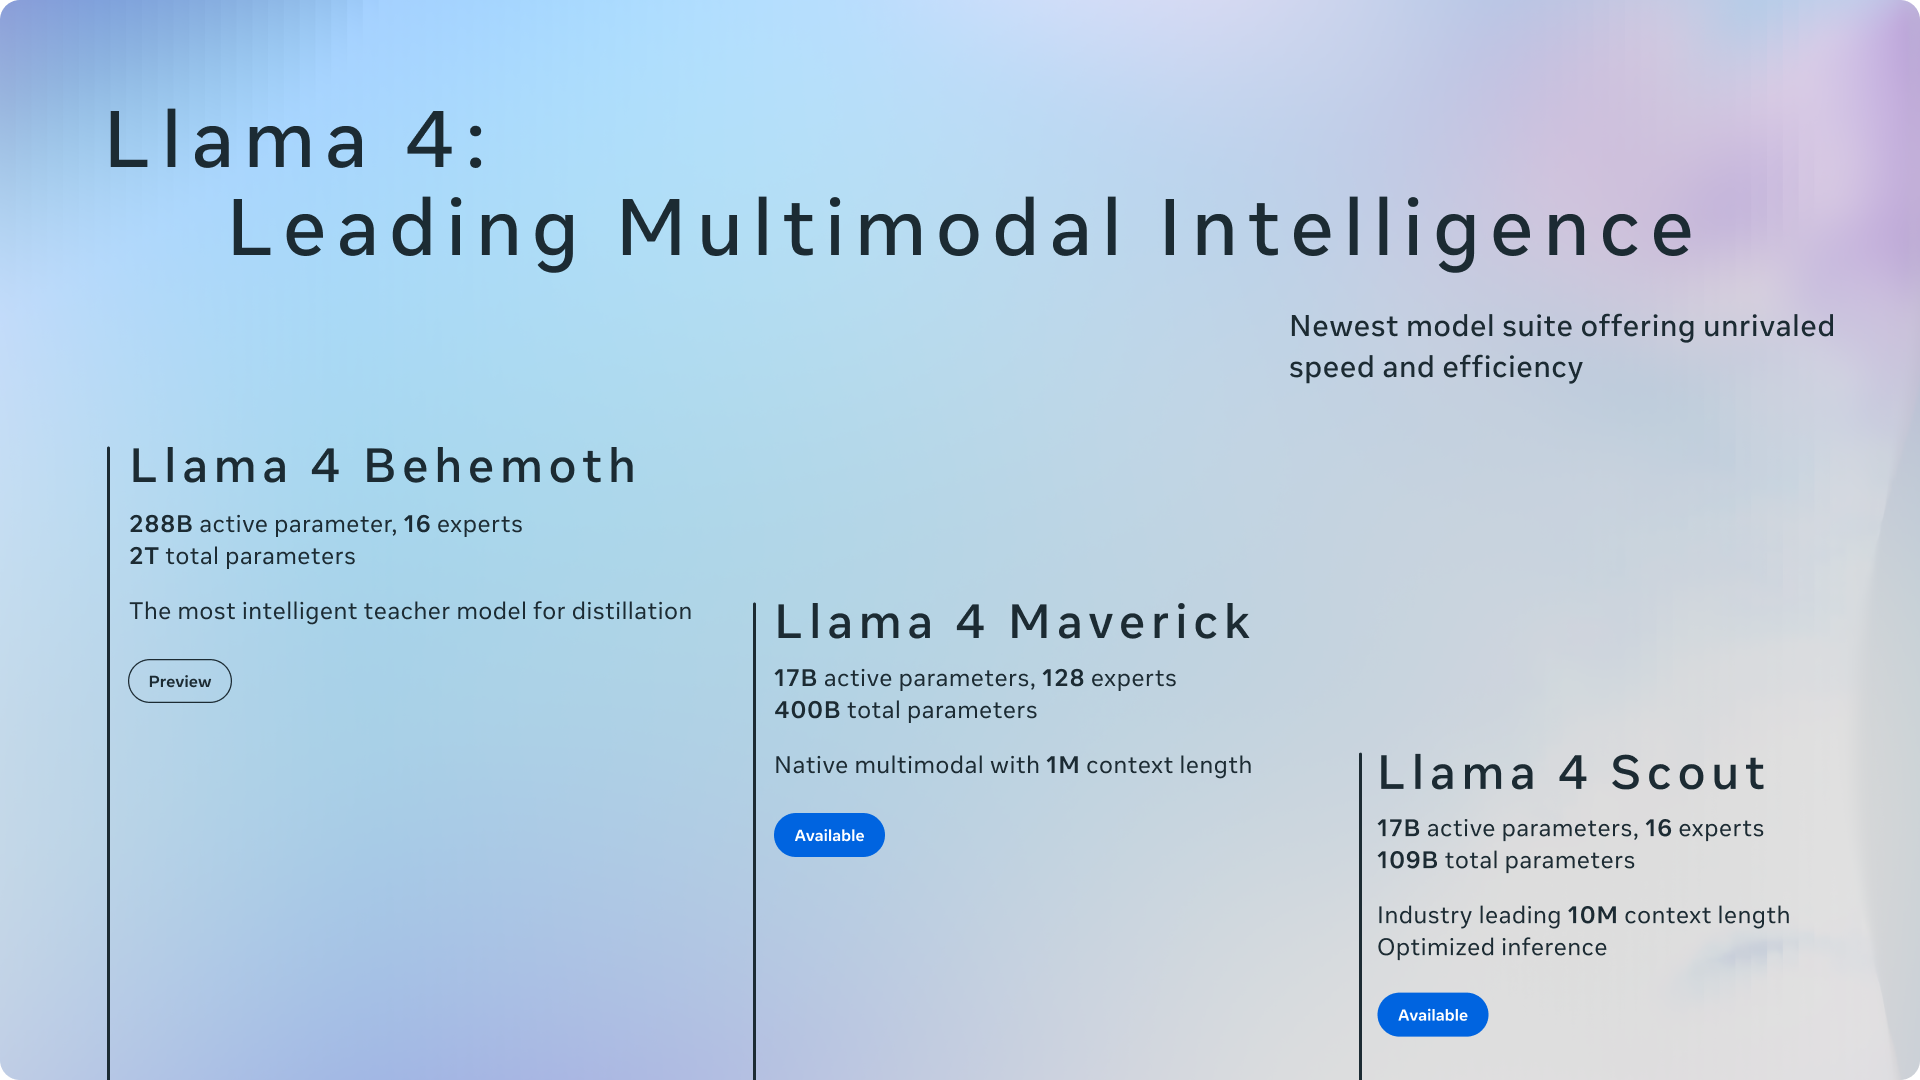
Teaser for The Llama 4 herd: The beginning of a new era of natively multimodal AI innovation

The Llama 4 herd: The beginning of a new era of natively multimodal AI innovation

Llama4 team

Models, 2025

Teaser for VGRP-Bench: Visual Grid Reasoning Puzzle Benchmark for Large Vision-Language Models

VGRP-Bench: Visual Grid Reasoning Puzzle Benchmark for Large Vision-Language Models

Yufan Ren, Konstantinos Tertikas, Shalini Maiti, Junlin Han, Tong Zhang, Sabine Süsstrunk, Filippos Kokkinos

Preprint, 2025

Teaser for Generalized Few-shot 3D Point Cloud Segmentation with Vision-Language Model

Generalized Few-shot 3D Point Cloud Segmentation with Vision-Language Model

Zhaochong An, Guolei Sun, Yun Liu, Runjia Li, Junlin Han, Ender Konukoglu, Serge Belongie

CVPR, 2025

Teaser for 3D-GPT: Procedural 3D Modeling with Large Language Models

3D-GPT: Procedural 3D Modeling with Large Language Models

Chunyi Sun*, Junlin Han*, Weijian Deng, Xinlong Wang, Zishan Qin, Stephen Gould

3DV, 2025

Teaser for DreamBeast: Distilling 3D Fantastical Animals with Part-Aware Knowledge Transfer

DreamBeast: Distilling 3D Fantastical Animals with Part-Aware Knowledge Transfer

Runjia Li, Junlin Han, Luke Melas-Kyriazi, Chunyi Sun, Zhaochong An, Zhongrui Gui, Shuyang Sun, Philip Torr, Tomas Jakab

3DV, 2025

Teaser for VFusion3D: Learning Scalable 3D Generative Models from Video Diffusion Models

VFusion3D: Learning Scalable 3D Generative Models from Video Diffusion Models

Junlin Han*, Filippos Kokkinos*, Philip Torr

ECCV, 2024

Teaser for Semantic Score Distillation Sampling for Compositional Text-to-3D Generation

Semantic Score Distillation Sampling for Compositional Text-to-3D Generation

Ling Yang, Zixiang Zhang, Junlin Han, Bohan Zeng, Runjia Li, Philip Torr, Wentao Zhang

Preprint, 2024

Teaser for Strong and Controllable Blind Image Decomposition

Strong and Controllable Blind Image Decomposition

Zeyu Zhang*, Junlin Han*, Chenhui Gou*, Hongdong Li, Liang Zheng

Preprint, 2024

Teaser for How Many Unicorns Are in This Image? A Safety Evaluation Benchmark for Vision LLMs

How Many Unicorns Are in This Image? A Safety Evaluation Benchmark for Vision LLMs

Haoqin Tu*, Chenhang Cui*, Zijun Wang*, Yiyang Zhou, Bingchen Zhao, Junlin Han, Wangchunshu Zhou, Huaxiu Yao, Cihang Xie

ECCV, 2024

Teaser for NeRFEditor: Differentiable Style Decomposition for 3D Scene Editing

NeRFEditor: Differentiable Style Decomposition for 3D Scene Editing

Chunyi Sun, Yanbin Liu, Junlin Han, Stephen Gould

WACV, 2024

Teaser for What Images are More Memorable to Machines?

What Images are More Memorable to Machines?

Junlin Han, Huangying Zhan, Jie Hong, Pengfei Fang, Hongdong Li, Lars Petersson, Ian Reid

Preprint, 2023

Teaser for Hyperbolic Audio-visual Zero-shot Learning

Hyperbolic Audio-visual Zero-shot Learning

Jie Hong, Zeeshan Hayder, Junlin Han, Pengfei Fang, Mehrtash Harandi, Lars Petersson

ICCV, 2023

Teaser for Curved Geometric Networks for Visual Anomaly Recognition

Curved Geometric Networks for Visual Anomaly Recognition

Jie Hong, Pengfei Fang, Weihao Li, Junlin Han, Lars Petersson, Mehrtash Harandi

TNNLS, 2023

Teaser for GOSS: Towards Generalized Open-set Semantic Segmentation

GOSS: Towards Generalized Open-set Semantic Segmentation

Jie Hong, Weihao Li, Junlin Han, Jiyang Zheng, Pengfei Fang, Mehrtash Harandi, Lars Petersson

The Visual Computer, 2023

Teaser for You Only Cut Once: Boosting Data Augmentation with a Single Cut

You Only Cut Once: Boosting Data Augmentation with a Single Cut

Junlin Han, Pengfei Fang, Weihao Li, Jie Hong, Ali Armin, Ian Reid, Lars Petersson, Hongdong Li

ICML, 2022

Blind Image Decomposition

Junlin Han, Weihao Li, Pengfei Fang, Chunyi Sun, Jie Hong, Ali Armin, Lars Petersson, Hongdong Li

ECCV, 2022

Teaser for CropMix: Sampling a Rich Input Distribution via Multi-Scale Cropping

CropMix: Sampling a Rich Input Distribution via Multi-Scale Cropping

Junlin Han, Lars Petersson, Hongdong Li, Ian Reid

Preprint, 2022

Teaser for Underwater Image Restoration via Contrastive Learning and a Real-world Dataset

Underwater Image Restoration via Contrastive Learning and a Real-world Dataset

Junlin Han, Mehrdad Shoeiby, Tim Malthus, Elizabeth Botha, Janet Anstee, Saeed Anwar, Ran Wei, Ali Armin, Hongdong Li, Lars Petersson

Remote Sensing (best paper award, top 0.1%), 2022

Teaser for Single Underwater Image Restoration by Contrastive Learning

Single Underwater Image Restoration by Contrastive Learning

Junlin Han, Mehrdad Shoeiby, Tim Malthus, Elizabeth Botha, Janet Anstee, Saeed Anwar, Ran Wei, Lars Petersson, Ali Armin

IGARSS (oral), 2021

Teaser for Dual Contrastive Learning for Unsupervised Image-to-Image Translation

Dual Contrastive Learning for Unsupervised Image-to-Image Translation

Junlin Han, Mehrdad Shoeiby, Lars Petersson, Ali Armin

NTIRE, CVPRW (oral), 2021

Blogs

Academic Services

Awards

Misc